# AlzDetect (HK-GenSpeech)
Early cognitive screening works better when it feels conversational and culturally local. The task was to open the doorway: keep rigor while inviting richer speech.
Overview
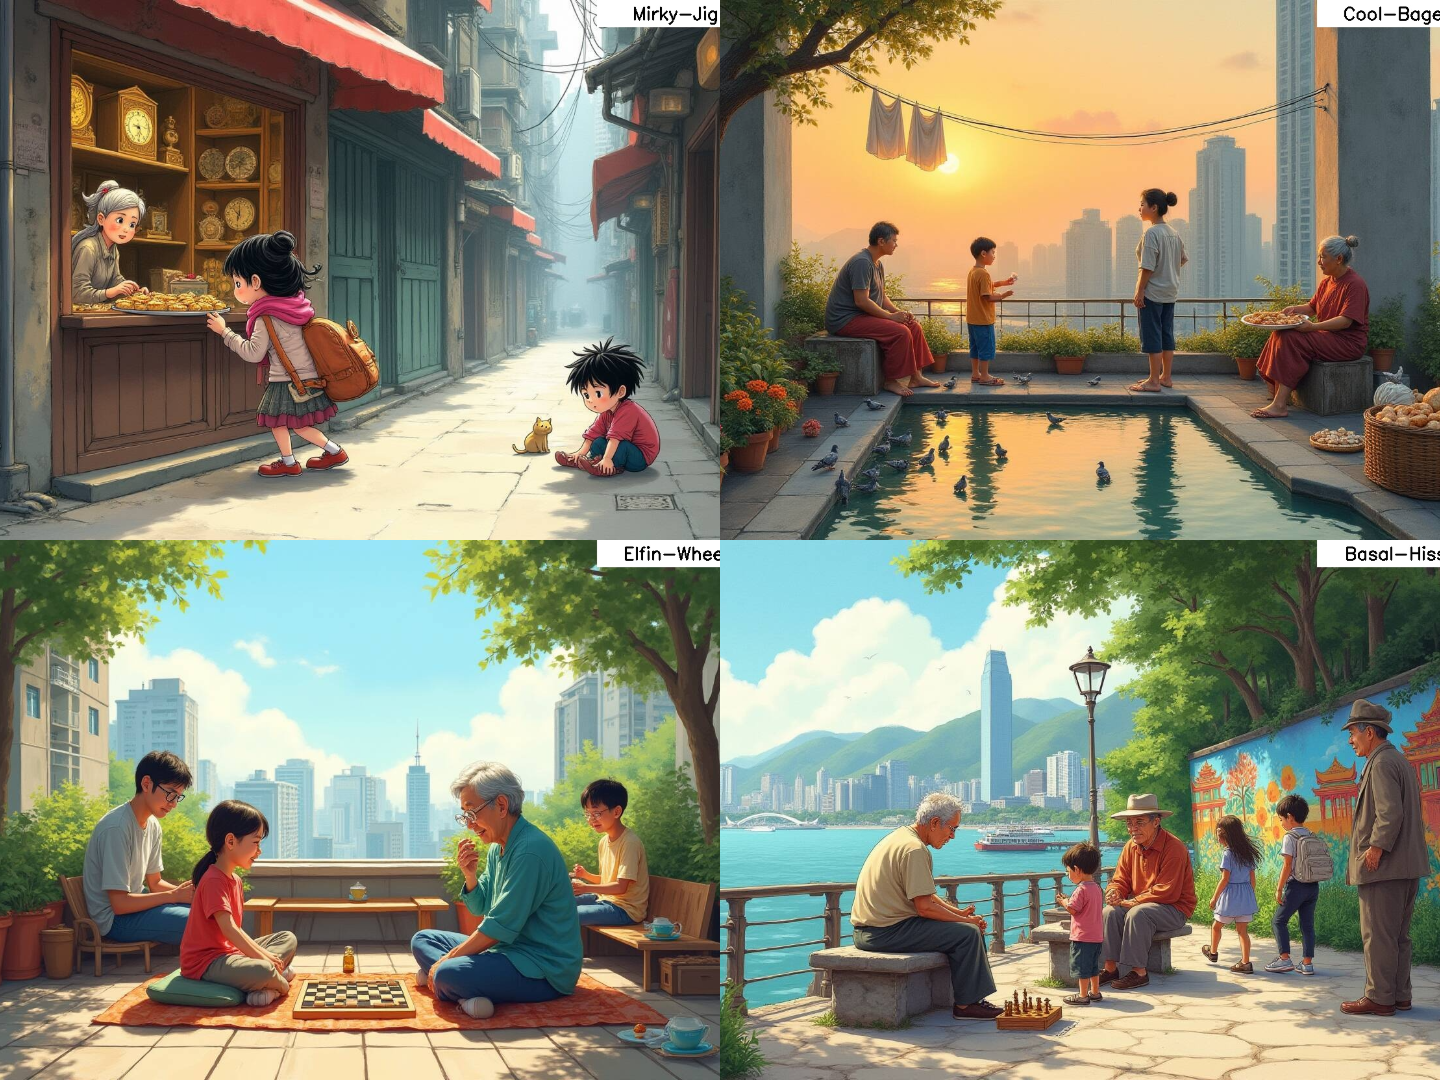
AlzDetect reimagines speech-based dementia screening so it works for the people who need it most. Rather than asking every patient to describe the same decades-old Cookie Theft illustration, we generate fresh scenes with local details and use them to spark more natural storytelling in Cantonese. The project pairs that generative pipeline — HK-GenSpeech — with lightweight clinic-friendly tooling so community health workers can run an assessment, capture audio, and review what the system heard. HK-GenSpeech starts by distilling the essential moments of the Cookie Theft scene (who is involved, what they are doing, why it matters) and weaving them into new prompts enriched with Hong Kong specific cues. GPT-4o, Llama 3, and Flux cooperate to turn those prompts into families of animated images that still test the same cognitive skills — reasoning about cause and effect, keeping track of characters, and explaining subtle visual details — but without the repetition that makes patients disengage. Working with seven elder-care centres and churches, we recorded 423 picture descriptions from 141 Cantonese speakers aged 55-94. Each person described the classic Cookie Theft picture, a standard HK-GenSpeech scene, and a personalised variant. When we trained Wav2Vec2 models on those recordings, AI-generated images proved just as reliable as the original illustration for estimating HK-MoCA scores, and mixing all three stimuli produced the lowest error and richest language.
Problem
One-size prompts constrain expression, create fatigue, and miss culturally specific cues that matter for clinical interpretation.
Approach
Generate localized image prompts and model speech with Wav2Vec2 to derive cognitive indicators. Collect a new Cantonese dataset and compare reliability/error against conventional baselines.
Impact
- * 423 descriptions from 141 Cantonese speakers (55-94) established a local evidence base.
- * AI-generated prompts matched baseline reliability while mixed stimuli reduced prediction error.
- * Pointed to next steps: longitudinal tracking and fairness checks across demographics.